Configuring Claude Code and Claude Desktop to Use Gemini via Antigravity Manager
2026-09-19As large language models rapidly evolve, developers often subscribe to different model ecosystems for distinct strengths—such as combining a Google AI Ultra subscription with the refined developer experience of Anthropic’s Claude Code CLI and Claude Desktop App.
However, integrating Claude-native clients with Google Gemini or Vertex AI backends presents two immediate challenges: protocol mismatch (Claude clients speak Anthropic Messages API, while Gemini speaks Google’s native API) and strict client-side validation (Claude Desktop blocks non-loopback HTTP and rejects non-claude-* model identifiers).
This guide walks through configuring Claude Code CLI and Claude Desktop App on Windows and macOS to seamlessly route through Antigravity Manager, an account-pooling reverse proxy running on a local server/NAS, backed by Gemini 3.8 Flash.
1. What is Antigravity Manager?
Antigravity Manager (community Docker image lbjlaq/antigravity-manager, powered by antigravity-tools) is an account-pooling and protocol-translation gateway tailored for Google Antigravity, Google AI Ultra, and Vertex AI backends.
Key Capabilities
- Multi-Account & Quota Pooling: Centrally aggregates multiple Google accounts (including Google AI Ultra/One subscriptions, OAuth sessions, and Vertex AI service credentials). It handles automatic session keep-alive, quota distribution, and seamless failover.
- Standardized Protocol Bridge: Translates Google backend responses into industry-standard Anthropic Messages API (
/v1/messages) and OpenAI API (/v1/chat/completions) formats. This allows any client built exclusively for Claude or OpenAI to consume Gemini models without code modifications. - Dynamic Model Aliasing (
custom_mapping): Allows wildcard routing rules at the gateway level. Incoming requests forclaude*orclaude-3-7-sonnetcan be dynamically mapped togemini-3.8-flash-high, cleanly bypassing client-side model validation and mitigating upstream rate limits (HTTP 429). - Web Administration Console: Provides a built-in web dashboard (default port
8045) to inspect health metrics, monitor query logs, configure model aliases, and set gateway access tokens.
[!NOTE]
Understanding the Gateway API Key
Google does not provide an “Anthropic API Key” for your Google account. In this setup, the API key entered into Claude Code or Claude Desktop is a self-configured proxy token (proxy.api_keyin Antigravity Manager). It protects your gateway from unauthorized local network access.
2. Architecture & Core Constraints

Essential Constraints to Know
- Network Constraint: Claude Desktop enforces a strict origin policy:
baseUrl: must use https (or http on loopback). Supplying a plain LAN IP address (such ashttp://192.168.68.55:8045) will be rejected by client validation. Forwarding to the local loopback (http://127.0.0.1:8045) satisfies this requirement. - Model Identifier Constraint: Claude Desktop uses a hardcoded regex pattern requiring all model routes to begin with
claude-*oranthropic/claude-*. Manually entering custom model names likegemini-3.8-flash-hightriggers validation warnings and disables the “Apply Changes” button. Transparent routing must instead be handled by the proxy’scustom_mapping.
3. Step 1: Gateway & Network Configuration
3.1 Configure Model Mapping on the Gateway
To allow Claude clients requesting claude or claude-3-7-sonnet to be automatically served by Gemini 3.8 Flash without quota exhaustion, set up mapping rules on your server.
Configuration file path: /home/<user>/.antigravity_tools/gui_config.json
Add or update the custom_mapping section under proxy:
1 | { |
Restart the container to apply the changes:
1 | sudo docker restart antigravity-manager |
(Alternatively, navigate to http://<SERVER_IP>:8045 in your browser and update the mapping via Proxy Settings → Custom Model Mapping.)
3.2 Retrieve Your Gateway API Key
Your clients require an authorization key (<ANTIGRAVITY_MANAGER_API_KEY>) to authenticate against Antigravity Manager:
- Via Web UI: Open
http://<SERVER_IP>:8045, go to Proxy Settings, and copy or set the API Key / Access Token. - Via Configuration File: Inspect the
"api_key"property insidegui_config.json:1
2
3
4
5{
"proxy": {
"api_key": "your_custom_proxy_key_here"
}
}
3.3 Set Up Local Loopback Port Forwarding
Forward port 8045 on your server to 127.0.0.1:8045 on your local workstation.
Windows (Native Portproxy, Persistent Across Reboots)
Open PowerShell as Administrator and execute:
1 | netsh interface portproxy add v4tov4 listenport=8045 listenaddress=127.0.0.1 connectport=8045 connectaddress=192.168.68.55 |
- Verify connection:
1
2netsh interface portproxy show all
Test-NetConnection -ComputerName 127.0.0.1 -Port 8045 - Remove rule (if needed later):
1
netsh interface portproxy delete v4tov4 listenport=8045 listenaddress=127.0.0.1
macOS (SSH Local Tunnel)
- Interactive Session:
1
ssh -N -L 8045:127.0.0.1:8045 <server_ssh_host>
- Background Daemon (LaunchAgent):
Create~/Library/LaunchAgents/com.user.antigravity-tunnel.plist:Load and start the service:1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
<plist version="1.0">
<dict>
<key>Label</key>
<string>com.user.antigravity-tunnel</string>
<key>ProgramArguments</key>
<array>
<string>/usr/bin/ssh</string>
<string>-N</string>
<string>-L</string>
<string>8045:127.0.0.1:8045</string>
<string><server_ssh_host></string>
</array>
<key>RunAtLoad</key>
<true/>
<key>KeepAlive</key>
<true/>
</dict>
</plist>1
launchctl load ~/Library/LaunchAgents/com.user.antigravity-tunnel.plist
4. Configuring Claude Code CLI
[!WARNING]
Claude Code prioritizes itssettings.jsonenvironment block over current shell environment variables. Setting temporary shell exports (export ANTHROPIC_BASE_URL=...) will be overridden by the config file. Modify the file directly.
4.1 Configuration File Setup
- Windows:
C:\Users\<YourUsername>\.claude\settings.json - macOS / Linux:
~/.claude/settings.json
Update the env section (replacing <ANTIGRAVITY_MANAGER_API_KEY> with your gateway key):
1 | { |
(Note: If a standalone "model": "sonnet[1m]" line exists at the root of settings.json, delete it so ANTHROPIC_MODEL within env handles routing.)
4.2 Verification Test
Run a quick probe command in any terminal:
1 | claude -p "Say 'Hello from Gemini 3.8 Flash'" |
Expected output:
1 | Hello from Gemini 3.8 Flash |
5. Configuring Claude Desktop App
5.1 Third-Party Inference Setup
- Open Claude Desktop, open Settings → Configure third-party inference.
- Select Gateway in the top dropdown.
- Under GATEWAY CREDENTIALS:
- Gateway base URL:
http://127.0.0.1:8045(do not append/v1) - Gateway API key:
<ANTIGRAVITY_MANAGER_API_KEY> - Gateway auth scheme:
bearer - Custom inference headers: Leave empty
- Credential kind:
Static API key
- Gateway base URL:
- Under MODELS:
- Model discovery: Enable (turn on). The proxy natively implements
GET /v1/models. Enabling this lets the client automatically discoverclaude-*model aliases. - Model list: Keep completely empty (if you manually added custom entries previously, remove them using the
×icon).
- Model discovery: Enable (turn on). The proxy natively implements
5.2 Bypassing UI Validation
Entering custom non-Anthropic model names manually causes Claude Desktop to display a validation error:
Doesn't look like an Anthropic model: expected a gateway model route referencing an Anthropic model...
This locks the Apply Changes button. Keeping the model list empty and relying on Model Discovery allows the gateway’s custom_mapping to handle transparent rewrites behind the scenes.
Click Test connection followed by Test model discovery, and then click Apply Changes.
5.3 Starting a Chat
Start a new chat in Claude Desktop. Keep the default model selected (or pick any Sonnet variant). All queries will now route seamlessly through Antigravity Manager to Gemini 3.8 Flash.
6. Troubleshooting & FAQ
Q1: Error: Model discovery — Invalid custom3p managed config: baseUrl: must use https (or http on loopback)
- Cause: The Base URL was configured with a LAN IP (e.g.,
http://192.168.68.55:8045). Claude Desktop enforces HTTPS for non-loopback addresses. - Fix: Use local port forwarding and configure the client with
http://127.0.0.1:8045.
Q2: Chat shows Model overloaded · Retrying (2/10) · 15s
- Cause: Requests to default Claude models hit rate limits (HTTP 429) on Anthropic accounts.
- Fix: Ensure
custom_mappingin the server’sgui_config.jsonmaps"claude*": "gemini-3.8-flash-high", and restart the Docker container.
Q3: Claude Code CLI returns Failed to authenticate. API Error: 401 Invalid API Key
- Cause: The value in
ANTHROPIC_AUTH_TOKENdoes not match theproxy.api_keyconfigured in Antigravity Manager, or stale credentials remained in~/.claude/settings.json. - Fix: Verify
proxy.api_keyingui_config.jsonand ensuresettings.jsonmatches exactly.
Q4: Connection drops after rebooting Windows
- Checks:
- Confirm the Windows
iphlpsvc(IP Helper) service is running. - Run
netsh interface portproxy show allin an elevated terminal to verify the forwarding rule is intact. - Ensure the server’s LAN IP address has not changed due to DHCP lease renewal.
- Confirm the Windows
Bringing the Legendary "grill-me" Skill into Mopheus: Teaching AI Agents Self-Questioning and Adversarial Review
2026-09-07Bringing the Legendary “grill-me” Skill into Mopheus: Teaching AI Agents Self-Questioning and Adversarial Review
The code is written, the architecture plan is signed off—but do you genuinely feel confident?
When massive traffic spikes hit, network blips occur, or edge-case anomalies emerge, where will your system fail first?
We rarely lack hands to write code; what we sorely lack is a rigorous, demanding, and uncompromising “reviewer.”

1. What is grill-me? Why is a Bare 60-Word Prompt Hailed as Legendary?
Among developers practicing AI-assisted coding and systems design, one skill is widely revered as a secret weapon: grill-me (literally meaning to put someone on the hot grill).
Created and open-sourced by renowned engineer and developer educator Matt Pocock:
- Original GitHub Repository: mattpocock/skills
- Original Skill Reference:
skills/grill-me/SKILL.md
This developer-favorite skill has an astonishingly concise definition file (SKILL.md)—just three sentences, roughly 60 English words:
1 | Interview me relentlessly about every aspect of this plan until we reach a shared understanding. |
Why is Such a Brief Prompt So Uncannily Powerful?
Those new to Prompt Engineering often assume that greater power demands labyrinthine, multi-page instructions. grill-me represents the pinnacle of minimalist design:
- “Relentlessly until shared understanding”:
Fundamentally dismantles LLMs’ default tendency toward sycophancy and superficial praise, instantly anchoring the Agent in the persona of a demanding Principal Architect or rigorous technical interviewer. - “Walk down each branch of the design tree”:
Forces systematic depth-first search across decision paths, knocking down architectural dependencies one by one rather than jumping erratically between surface-level topics. - The Core Anchor: “MUST provide your recommended answer”:
This is the stroke of genius in the prompt. If an AI merely asks questions, it easily devolves into an annoying contrarian. But by mandating that every critique must come paired with a concrete recommendation, the model is forced to simulate trade-offs and evaluate alternatives simultaneously. This drastically lowers cognitive overhead for the person being grilled and instantly establishes a high-quality reference baseline. - “Ask one at a time” & “Explore the codebase instead”:
The former prevents cognitive overload by avoiding daunting walls of text; the latter keeps the AI pragmatic and grounded, ensuring it never wastes human time on facts already verifiable in code.
2. Why Forge grill-me into a Native Ticket Mechanism in Mopheus?
Mopheus natively supports Agent Skills. So why go through the effort of engineering a dedicated native Griller inquiry and review mechanism right within ticket comment threads?
The Reality of Human-Agent Grilling: Invaluable, Yet Cognitively Exhausting
The original grill-me fundamentally operates as “Agent grilling Human.” An engineer sits at their keyboard, engaging in a live, back-and-forth dialogue with the Agent.
A standard grill-me session typically spans 10 to 20 rounds of probing inquiries, taking roughly 30 minutes.
In practice, this is awe-inspiring yet mentally intense: when questioned on the 10th consecutive sharp edge case, one genuinely begins to feel the heat of the grill.
Yet there is no question: this process is immensely worthwhile—especially for core feature designs, complex online database migrations, or distributed systems architecture, where catching catastrophic vulnerabilities before writing code saves days or weeks of firefighting later.
The Dilemma: How to Run a “Faster Round” Without Sacrificing Depth?
Crucial as deep review is, we cannot afford to lower standards simply because the process is demanding. In fast-paced daily development, teams often need to run a rapid Grill cycle, ruthlessly uncovering hidden risks in designs and code in minimal time.
Moreover, in an AI-Native engineering organization, much of the design proposals and pull requests are already written by execution Agents. Having the same Agent review its own work introduces obvious confirmation bias. Meanwhile, waiting for human engineers to schedule a 30-minute synchronous interview for every PR or design detail creates severe delivery bottlenecks.
We needed rigorous reviews to be automated, high-frequency, and continuous.
This sparked an intuitive realization: What if we assign an independent, specialized critique Agent to “interview itself” in the background across 20 rounds of deep reasoning?
The Core Solution: Autonomous Self-Questioning and Adversarial Review
By dispatching dedicated specialist Agents (e.g., DBA Guardians, Security Auditors, High-Concurrency Architects) as visiting experts, Mopheus conducts autonomous multi-round Self-Q&A sessions directly against any proposal or discussion thread.
1 | Workflow Evolution in Mopheus: |
This means: A human engineer simply clicks a button on a ticket, and an agent conducts the entire adversarial review in a background sandbox within minutes, presenting a structured stress-test report right under the thread for rapid team consensus.

3. What If Humans Still Want to Be Grilled Personally? Absolutely Supported!
Making Griller a native ticket mechanism in no way detracts from the value or thrill of human engineers undergoing the challenge themselves.
If you are a Tech Lead or Principal Architect designing a mission-critical system and want to experience AI’s trial by fire directly, doing so in Mopheus is straightforward:
- Import or Create Classic Skills: Create or import the original
grill-mein the Mopheus Skill Hub, or import the advancedgrill-with-docs(which grills your design while incrementally updating the project’sCONTEXT.mdglossary andADRArchitecture Decision Records based on reaching consensus); - Engage in Live Dialogue:
- In Chat: Start an interactive session with an architect agent and invoke
/grill-mefor real-time stress testing; - In Tickets: Open an architecture design ticket, @mention your agent in a comment with instructions, and engage in public, round-by-round review within the thread.
- In Chat: Start an interactive session with an architect agent and invoke
1 | Dual-Track Review System: |
4. How We Built It: Clean, Elegant, and Pragmatic Engineering
To seamlessly weave rigorous grilling into daily workflows, we adhered to disciplined, minimalist engineering principles:
1. Agents as Grillers: Non-Invasive Role Specialization
We avoided bloating the system with complex configuration layers. Enabling is_griller in an agent’s profile (or passing --is-griller via the CLI) immediately qualifies that agent as a Reviewer.
The agent naturally leverages its domain specialization:
- DBA Griller: Unpacks slow queries, deadlocks, missing indexes, and unsegmented transaction risks;
- Architecture Griller: Audits service decoupling, fallback circuits, and state machine transitions;
- Frontend Griller: Tests responsive boundaries, accessibility, and UI race conditions.
Regardless of whether a ticket is assigned to a human or another Agent, users can summon them on demand as “visiting experts” without disrupting the ticket’s primary ownership.
2. Precise Prompt Scoping and Closed-Loop Threading
To ensure agents remain grounded and avoid hallucinations during self-Q&A, we instituted three fundamental prompt rules:
- Thread Scoping: The Griller strictly consumes the targeted comment and its immediate conversational context as ground truth;
- Language Matching: If the source discussion is in Chinese, the entire self-Q&A and final critique are generated in Chinese; if in English, it outputs English, preserving conversational consistency;
- Thread Reply: The finished report automatically mounts as a nested child response (
--parent) beneath the original comment, matching GitHub PR review cleanliness.
3. CLI-First Design and Real-Time Awareness
Developers can summon a Griller with one click in the Web UI:

Or directly trigger reviews from terminal CLIs or CI/CD pipelines:
1 | # Launch a deep Grill review on a comment with a designated DBA Griller |
Backed by real-time WebSocket event dispatching and browser tab wake-up reconnects, review tasks update seamlessly whether an engineer stays focused on the tab or returns later.
5. Future Roadmap: From Single-Agent Self-Q&A to the “Agent Arena Topic”
Autonomous Self-Q&A in isolated sandboxes has already delivered substantial quality gains, but it is only the prelude to true multi-agent adversarial collaboration.
Our next milestone is enabling two fully independent agents to engage in real-time, face-to-face cross-examination:
- Dispatching a dedicated Reviewer Agent to directly grill a Developer Agent preparing to write code;
- Directing Security and SRE Reviewer Agents to cross-examine a DBA Agent planning high-risk data migrations or online maintenance.
To realize this vision, we are designing the Agent Arena directly atop Mopheus’s existing Topic deliberation framework:
1 | Future Roadmap: Agent Arena Topics |
By elevating ticket discussions into Arena Topics, human engineers can observe high-level algorithmic debate in real time while securing thoroughly stress-tested, resilient architectural designs.
6. Conclusion: Toward Software Engineering Driven by AI Adversarial Evolution
As LLMs generate code with breathtaking speed, the true bulwark of software engineering shifts toward review and verification.
Bringing grill-me into Mopheus represents a pivotal milestone in multi-agent adversarial collaboration:
- It preserves the training ground where humans can personally undergo AI’s rigorous cross-examination;
- It introduces automated quality checkpoints where agents asynchronously self-question and poke holes in human and AI proposals alike;
- And it sets the stage for genuine dual-agent sparring inside Arena Topics.
Ready to empower your engineering workflows with relentless, professional Griller agents?
Explore Mopheus (mopheus.ai) and equip your workspace with dedicated architecture and quality guardians today!
Why Mopheus Truly Unifies Dev and Ops: Moving from Fragmented Toolchains to an AIDevOps Agent Workspace
2026-09-07Why Mopheus Truly Unifies Dev and Ops: Moving from Fragmented Toolchains to an AIDevOps Agent Workspace
From Siloed Toolchains to a Unified AIDevOps Agent Workspace

1. Introduction: The Forgotten Promise of DevOps and the “Tool Silo” Dilemma
Over the past decade, software engineering organizations have relentlessly pursued the ideals of “DevOps (unifying development and operations)” and automated continuous delivery. Yet when examining the daily reality of modern development teams—especially agile teams ranging from dozens to hundreds of engineers—we often uncover a friction-filled reality of multi-system fragmentation:
- Dev (Development Domain): Immersed in GitHub / GitLab, IDEs, local repositories, and CI build pipelines;
- Ops / ITOM (Operations Domain): Staring at Prometheus, Grafana, APM distributed tracing, ELK logs, or cloud provider consoles;
- ITSM (Process Domain): Manually filling out release tickets, change reasons, risk assessments, and approval forms in standalone workflow platforms;
- AIOps (Intelligent Operations): Positioned as an algorithmic patch bolted onto the Ops side, merely performing reactive time-series clustering and alert deduplication after massive alert storms occur.
1 | Traditional Fragmented Architecture: |
Engineers are forced to shuttle between 4–5 disparate systems, copy-pasting commit links, manually checking approval boxes, and troubleshooting alerts stripped of contextual code history. Dev and Ops may now sit in the same room organizationally, but across toolchains and cognitive contexts, an impassable chasm remains.
More importantly: “AIOps” itself is a transitional concept. If AI operates purely on the Ops side analyzing time-series metrics and logs without understanding the repository’s Abstract Syntax Tree (AST), domain requirements, or architectural decisions, it will forever remain limited to pointing out symptoms rather than resolving root causes.
True next-generation software engineering will not be confined to AI-driven Ops; it must encompass full-lifecycle AIDevOps (Agentic DevOps).
2. The Core Paradigm: Why LLM Agents Can Eliminate the Chasm
Why have past automation tools (such as scripts and rule engines) failed to fundamentally unify Dev and Ops?
Because traditional tools lack cross-domain semantic understanding—Prometheus parses numbers, Git tracks text diffs, and SonarQube enforces static syntax rules. None can hold a coherent dialogue with one another.
In contrast, AI Agents possess full-stack semantic permeation:
- An Agent can comprehend a Product Manager’s natural language requirements and generate business code adhering to architecture constraints;
- An Agent can interpret a production APM stack overflow trace, trace it back to a commit merged 10 minutes ago, and generate an executable bugfix patch.
Under the AIDevOps paradigm:
- ITSM is embedded as automated pipeline gatekeeper rules;
- ITOM becomes the sensory perception layer for agents;
- AIOps evolves into an active, self-healing agent capable of autonomous remediation.
3. Mopheus: A Collaborative Hub Built for AIDevOps
Mopheus was conceived to operationalize this native “People, Agents, Teams” collaboration paradigm in real-world software engineering.
Mopheus is not another shallow chat box. It is an AI-native Workspace that deeply unifies task management, sandboxed code execution, automated pipelines, and long/short-term memory.
1 | ┌──────────────────────────────────────────────────────────────┐ |
Four Core Pillars Powering Mopheus’s Dev & Ops Unification:
1. Polymorphic Assignees: Equal-Footing Collaboration Between Humans and Agents
In Mopheus, assignees for a Ticket (task, feature, or bug) are polymorphic: they can be human engineers (Members), autonomous AI Agents (Agents), or multidisciplinary teams composed of specialized agents (Teams).
Requirements analysis, code implementation, release verification, and incident diagnosis flow through the same board and issue trail, eradicating the fragmentation of “code in GitHub, planning in Jira, operations in ITSM.”
2. Local Daemon & Grounding in Real Runtimes
Whether an AI can handle Dev and Ops hinges on whether it operates within real execution environments. The Mopheus Daemon links the workspace to local or containerized sandboxes housing agent CLIs (supporting Claude, Codex, KimiCode, DeepSeek Harness, Pi, and other native runtimes):
- Agents do not hallucinate fixes in isolation; they compile source trees, execute unit and integration tests, run database migrations, and pull runtime logs inside isolated Git worktrees and shell sandboxes.
3. Event-Driven Automation & Closed-Loop Self-Healing
Deeply integrating GitHub Webhooks, a cron scheduling engine, state transition triggers, and ChatOps (Feishu, DingTalk, Slack), Mopheus awakens bound agents the instant an alert fires or a CI build fails, spinning up an isolated sandbox to perform diagnosis.
4. Vector and Graph-Based Long-Term Memory
Powered by PostgreSQL and pgvector, Mopheus maintains long-term memory spanning system architecture, historic code diffs, production incidents, and post-mortems. When diagnosing an Ops incident, an agent retrieves historical Dev design decisions; when writing Dev code, it learns from prior Ops failures.
4. Real-World Walkthrough: Daily Workflows Under AIDevOps
In an engineering team powered by Mopheus, the journey from an initial requirement or bug report to local coding, continuous integration, lightweight release, and production observability forms a seamless closed loop:
Phase 1: Full-Lifecycle End-to-End Workflow

- Requirement Ingestion & Smart Decomposition: The PM creates a requirement ticket in Mopheus. An agent consults the project memory repository to complete acceptance criteria and decompose subtasks.
- Local Development & Automated Verification: Coordinated through agent team orchestration, an agent branches out a feature worktree. Mopheus Daemon drives local runtimes to implement business logic and unit tests, opening a PR linked to the ticket.
- Review & Continuous Integration: CI runs tests and builds. The agent provides automated first-pass code reviews. Once peer reviews pass, changes merge to the main branch.
- Lightweight Change & Deployment (Replacing Legacy ITSM): Merging code triggers the release pipeline. Notifications post to ChatOps channels, tech leads approve with a click, and automated audit trails accompany rolling container updates.
- Observability, Intelligent Triage & Lifecycle Closure: The pipeline writes a deployment marker, the ticket transitions to Done, and ITOM continuously tracks operational metrics.
Phase 2: The Cross-Domain Self-Healing Loop During Incidents
When an anomaly hits production, traditional fragmented setups require war rooms and multi-tier ticketing; in Mopheus, the barrier between Dev and Ops vanishes, enabling sub-minute automated response:

- Event Ingestion: A spike in error rates or latency triggers Mopheus via webhook. A high-priority incident ticket is automatically created and assigned to an on-call triage agent.
- Code-Level Root Cause Attribution: The agent leverages its sandbox to analyze crash stacks and APM traces, comparing them against the Git diff of the latest deployment to isolate offending code.
- Automated Hotfix Generation: In an isolated sandbox, the agent branches a hotfix, writes the patch, adds regression tests, and submits a fix PR.
- Human-in-the-Loop Confirmation & Instant Resolution: Mopheus posts an actionable diagnostic report and PR link to the team channel. Upon engineer sign-off, the PR merges and deploys, metrics recovers, and the incident ticket automatically closes.
5. Traditional Model vs. Mopheus AIDevOps Comparison
| Dimension | Traditional Model (ITSM + ITOM + AIOps + DevOps) | Mopheus AIDevOps Model |
|---|---|---|
| System Footprint | 4–5 disjointed systems requiring manual synchronization | 1 unified AI-native engineering workspace |
| Collaboration Role | Humans act as “data couriers” and “form fillers” | Humans act as Approvers; Agents act as End-to-End Executors |
| Change Compliance | Tedious ITSM form-filling dragging release cycles to days | PR and pipeline gates provide built-in compliance and instant sign-off |
| Incident Triage & Fix | Alerts show symptoms; engineers comb logs for code links | Agents trace stacks directly to source code and open executable hotfix PRs |
| Knowledge Capture | Post-mortems rot in static docs; future outages repeat old mistakes | Knowledge is automatically vectorized into durable, reusable agent memory |
6. Conclusion: The Next Frontier of Software Engineering is Agent-Native
The ultimate goal of DevOps has never been accumulating more tools, but eliminating friction along the delivery pipeline so high-quality code can safely reach production along the shortest possible path.
In the AI era, slicing operations into AIOps, compliance into ITSM, and coding into isolated IDEs no longer meets the demands of modern productivity. Mopheus anchors its core in task graphs, operates through agent runtimes, and reasons through memory graphs, truly unifying Dev and Ops into a singular discipline.
For modern software teams, embracing AIDevOps means more than a multiplier on engineering efficiency—it equips every engineer with an autonomous, 24/7 digital engineering team that understands your business, your architecture, and your operational realities.
Ready to tear down the silos between Dev and Ops and experience sub-minute self-healing software delivery?
Explore Mopheus (mopheus.ai) and build your autonomous digital engineering organization today!
Layered Intelligence in the AI Era: The Design Philosophy of Agent-Skill Architecture
2026-03-11Layered Intelligence in the AI Era: The Design Philosophy of Agent-Skill Architecture
Introduction: A Database Operations Scenario
It’s 3:00 AM, and a production database alert goes off.
The Traditional Approach (Status Quo):
- The On-call DBA is woken up by a phone call.
- VPN connection → Jump Server → Production Server.
- Manually execute 10+ diagnostic SQL queries.
- Stare at dense query results in a terminal window.
- Rely on intuition to identify the problem, perhaps digging through documentation or historical tickets.
- Organize the data and write a diagnostic report.
- Total elapsed time: 30-60 minutes, while praying for no human error.
With a Generic AI Assistant (An incremental improvement):
1 | > ChatGPT, help me analyze the performance issues on this database. |
The Agent-Skill Architecture (Our solution):
1 | > Background: Start yashandb-ops agent, check 'dev-kamus' database space usage. |
This isn’t science fiction; it’s a real-world scenario we just verified. Reducing the time from 30 minutes to 2 minutes, from serial to parallel, and from manual judgment to intelligent analysis—behind it all is a meticulously designed Agent-Skill Layered Architecture.
I. The Three Eras of Operations
1.1 The Traditional Era: Manual + Scripts + Manually Coded Products
Most enterprises today use mature operations products, yet we still consider this the “Traditional Era.” Moving from manual commands to scripts and UIs is progress, but the capability behind these products remains manually engineered, not autonomously understood and invoked by machines.
Let’s look at the evolution: Purely manual → Scripting → Operations Products.
The DBA’s Manual Workflow:
1 | # DBA hand-cranked workflow |
The Scripting Attempt:
Scripts solved repetition but introduced new problems:
- Lack of Intelligence: Rigid execution without the ability to adjust based on results.
- Maintenance Hell: SQL logic scattered across various script files.
- Unreadable Results: Output is raw text and requires manual interpretation.
- Zero Interaction: Cannot drill down based on initial findings.
Platform like pgAdmin, Oracle Enterprise Manager, or Prometheus + Grafana encapsulate scripts into a friendlier UI, but the core remains: experts hard-code the logic line by line.
In essence, the traditional paradigm is:
1 | if Metric A > Threshold: |
These systems handle only what the designer anticipated. They can “display” but not “understand”; “alert” but not “diagnose”.
The Divide: The difference between the traditional era and the AI era isn’t “whether you have automated products,” but rather “is the capability hard-coded, or is it encapsulated into a Skill that an Agent can invoke dynamically?”
1.2 The Generic AI Assistant Era: Intelligent, but Not Professional
ChatGPT and Claude give DBAs hope, but practical issues remain:
- No Active Execution: AI acts as “advanced documentation,” requiring humans to run SQL and paste results.
- Context Pollution: Long query results fill the context window, causing the AI to lose the thread.
- Lack of Domain Depth: Generic AI knows “what” things are but lacks specific diagnostic SQLs and expert optimization experience.
- Serial Execution: Cannot handle multiple dimensions (space, performance, locks) simultaneously in a single chat thread.
The RAG Limitation: Many look to RAG (Retrieval-Augmented Generation) as the final answer. While RAG increases knowledge density, it solves Knowledge Retrieval, not Execution and Orchestration. RAG is a vital component, but not the ultimate architecture. It moves AI from “generic answers” to “documented answers,” but not yet to “task completion.”
1.3 The Agent-Skill Architecture Era: Professional + Intelligent + Parallel
This is the architecture we are introducing. Here is a comparison:
| Dimension | Traditional Ops | Generic AI Assistant | Agent-Skill Architecture |
|---|---|---|---|
| Execution | Manual | AI Guided, Human Executed | AI Auto-Executed |
| Knowledge Depth | Individual Experience | Generic Knowledge | Domain Expert Level |
| Parallelism | None (one pair of hands) | None (Serial chat) | Native Support |
| Response Speed | 30-60 minutes | 15-30 minutes | 2-5 minutes |
| Consistency | Varies by person | Decent | Fully Consistent |
| Error Rate | Medium (Fatigue/Skill) | Medium (Understanding) | Low (Standardized Flow) |
II. The Architecture Dilemma of Generic Assistants
The problem isn’t just “intelligence.” It’s that the monolithic architecture of generic assistants isn’t designed for professional task execution. It mixes understanding, reasoning, knowledge calling, and tool use into a single flow. Professional database ops requires multi-step diagnosis and dynamic decision-making that a single chat thread can’t reliably handle.
III. Agent-Skill Architecture: Layered Intelligence
Our solution is a three-layer architecture:

3.1 Layer 1: The Orchestrator
Responsibility: Understand user intent, decompose complex tasks, and route them to the appropriate executors.
1 | class OrchestratorAgent: |
3.2 Layer 2: Specialized Agent
Responsibility: Execute tasks within a specific domain by calling the relevant Skills.
1 | class YashanDBOpsAgent: |
3.3 Layer 3: Skill
Responsibility: Encapsulate specific professional knowledge and execution logic.
1 | class YashanDBSpaceSkill: |
IV. Architectural Advantages: Why This Design?
4.1 Separation of Concerns
Every layer does one thing. Orchestrator routes, Agent calls, and Skill executes professional diagnosis logic.
4.2 Parallel Execution
In real tests:
- Space check: 99s
- Wait event analysis: 110s
- Parallel Total: 110s (vs 209s for sequential)
4.3 Context Isolation and Depth
Each Skill has its own context window. The “Space Skill” window is not polluted by lock data or general coding knowledge, keeping the AI focused on expert database metrics.
4.4 Extensibility and Evolution
Adding new functionality takes three simple steps:
- Create a new Skill (e.g.,
IndexAdvisorSkill). - Register it to the Agent.
- Update Orchestrator routing (often automatic).
V. AI Era Design Philosophy
5.1 From “General” to “Precise”
Traditional software seeks “monolithic” apps. AI era needs modular intelligence.
5.2 Conway’s Law in AI Architecture
Melvin Conway stated that systems reflect organization structure. In AI:
Expert Mindset → Skill Modules → Agent Boundaries → Orchestrator Routing.
Our system mirrors the DBA’s specialized mindset: Space, Performance, Locks.
5.3 Unix Philosophy Reborn
- Do one thing well (Specialized skills).
- Design for composition (Agents combine skills).
Every Skill is like a Unix command—focused and reusable.
VI. Real-World Case: Database Diagnosis in Two Minutes
6.1 User Input
“Start yashandb-ops agents in background to check space and wait events on dev-kamus.”
6.2 Orchestrator Processing
It identifies intent_1 (space) and intent_2 (wait events) and dispatches them to parallel background agents.
6.3 Agent & Skill Execution
Agent 1 calls the SpaceSkill. It queries tablespace usage, file status, large objects, and fragmentation. It then synthesizes these into a structured SpaceReport. Agent 2 does the same for wait events simultaneously.
6.4 Result Presentation
110 seconds later, the user receives structured reports with warnings (e.g., SYSTEM tablespace at 80.1%) and actionable SQL recommendations.
VII. Design Principles & Best Practices
7.1 Skill Design Principles
- Single Responsibility (SRP): Avoid “God Skills”.
- Interface Consistency:
1
2
3
4
5class BaseSkill(ABC):
def execute(self, **params) -> Report:
"""Execute and return structured report"""
pass - Knowledge Encapsulation: Encapsulate Declarative (SQL), Procedural (Flows), and Empirical (Best practices) knowledge.
7.2 Agent Design Principles
- Domain Focus: One agent per database type (PostgreSQL vs MySQL).
- Statelessness: Let Skills or external storage manage state.
7.3 Orchestrator Design Principles
- Intelligent Routing: Understand dependencies and automate parallelism.
- Graceful Fallback: Downgrade from specialized agents to generic handlers or human escalation if an agent fails.
VIII. Future Outlook: Self-Evolving Systems
8.1 Auto-Generation of Skills
The Orchestrator could generate a new DeadlockDetectionSkill on the fly by processing documentation and existing lock knowledge.
8.2 Collaborative Agent Networks
Agents interacting to share context.

8.3 Continuous Knowledge Accumulation
Every execution is a learning opportunity.
1 | class EvolvingSkill: |
IX. Conclusion: Architecture as Philosophy
The Agent-Skill architecture is about Divide and Conquer, Professionalism, and Compositional Innovation. It ensures AI is deeper, faster, more isolated, and ready to evolve.
Tech Stack: Claude 4.6 (Sonnet) + Agent SDK + yashandb-cli + Python
Interested in AI architecture? Follow my blog at kamusis.me for more deep dives.
Built-in Multi-Agent Grok 4.2.0: When LLMs Learn Self-Play and Real-Time Evolution
2026-02-22Built-in Multi-Agent Grok 4.2.0: When LLMs Learn Self-Play and Real-Time Evolution
Introduction: A Turning Point in AI Reasoning Paradigms
On February 17, 2026, xAI launched the public beta of Grok 4.2.0 (often referred to as Grok 4.20). Over the past year, most of the noise in the LLM world has been about bigger models and bigger context windows. Grok 4.2.0 is interesting for a different reason: it treats reasoning as a coordinated process rather than a single, monolithic pass.
The pitch is straightforward: instead of one “omniscient black box,” you get a small team of specialized agents that argue, check, and reconcile before you see an answer. In other words, it leans into multi-agent self-play as a first-class design choice. Below is a breakdown of what xAI appears to be doing, and why it matters in practice.
Core Capabilities: The “Four-Headed Dragon” Architecture at the Reasoning Layer (Multi-Agent System)
The headline feature of Grok 4.2.0 is a built-in four-agent collaboration setup. Traditional chat models generate token after token in a single stream; Grok 4.2.0 frames the process more like an internal roundtable that happens before it commits to a final response.
These four personas share the same base model weights, but they run with different roles and prompts, trained through Multi-Agent Reinforcement Learning (MARL):
Grock (The Captain)
As the primary agent, Grock is responsible for understanding the user’s original intent, breaking down tasks, and, as discussions draw to a close, handling conflict mediation and summarizing the final answer. He is the brain and metronome of the entire system.Harper (The Truth-Seeker) —— Fact Checker & Intelligence Officer
Harper is the fact-checking and retrieval piece. The claim is that it can tap into a live feed from X (Twitter) with very low latency, and that it stays focused on one job: getting concrete, up-to-date details. In practice, this is the part that makes the system feel “online” rather than purely generative.Benjamin (The Logic) —— Logic & Engineering Expert
Benjamin is the rigorous mathematics, coding, and logical reasoning expert. When Grock assigns technical tasks, or when Harper throws out potentially contradictory data, Benjamin is responsible for code generation, mathematical derivations, and strict logical validation. It serves as the “stress-testing machine” for all information.Lucas (The Creative/Contrarian) —— Creative Divergent & “Devil’s Advocate”
Lucas is trained to push back. He looks for edge cases, alternative explanations, and the annoying-but-useful objections that prevent the whole system from collapsing into a bland consensus. If the setup works, this is one of the more practical ways to reduce confident nonsense.
Deep Dive: Why is the “Internal Debate Mode” an Inevitable Path to AGI?
Mixture of Experts (MoE) uses a router to send tokens to different expert networks. Grok 4.2.0’s framing is closer to a “Mixture of Agents”: parallel roles debating and cross-checking, then merging into a single answer.
Emergent Synergy
The idea is simple: internal deliberation can catch mistakes that slip through a single-stream generation. When a question is ambiguous, having agents disagree first is often better than forcing one voice to sound certain.Pushing Reasoning Efficiency to the Limit
The obvious concern is cost. Multi-agent systems can get expensive fast if you treat them like four separate models. xAI’s argument is that weight sharing, KV cache reuse, and fast internal synchronization keep the overhead closer to 1.5 to 2.5x a single model, which is at least in the realm of “deployable” rather than “research-only.”The Ultimate Solution for Real-Time (The Real-Time AI)
If Harper’s retrieval is as responsive as advertised, it helps with the one thing chat models usually struggle with: breaking, fast-moving events. That doesn’t automatically make the model right, but it can make it less outdated.
Practical Performance: Dominance in the Alpha Arena
Theory is cheap, so the real question is how this behaves in a competitive setting. In the Alpha Arena Season 1.5 stock trading and prediction simulation, Grok 4.2.0 reportedly performed unusually well.
In an environment where multiple models competed side-by-side, Grok 4.2.0 was described as the only family to sustain profitability, with an absolute profit rate around 35% over a few weeks. The multi-agent story here is plausible: Harper watches for fast shifts in sentiment, Lucas challenges whether the signal is a trap, Benjamin tries to validate it with backtests and models, and Grock makes the call. If nothing else, that loop is a decent recipe for filtering the worst social-media noise.
Conclusion: Marching Towards Transparency and Autonomy
Grok 4.2.0 is a clear signal that xAI is betting on an “agent-as-a-model” direction. Instead of pushing a single black box harder and hoping hallucinations go away, it leans on division of labor: one part retrieves, one part reasons, one part argues, and one part decides.
Whether this becomes the standard path to AGI is still an open question. But as a product design choice, multi-agent reasoning is easy to understand, and it lines up with what many users actually want: fewer confident mistakes, more explicit checking, and answers that feel like they were thought through.
References
Mastering Oracle Database Connectivity for SQLcl MCP Server
2026-02-03Mastering Oracle Database Connectivity for SQLcl MCP Server
The SQLcl MCP Server is a powerful bridge that brings the capabilities of Oracle SQLcl to the world of AI agents and large language models (LLMs). By leveraging the Model Context Protocol (MCP), it allows your AI environment to interact directly with Oracle Databases. However, for this interaction to be seamless and secure, proper connection management is essential.
In this post, we’ll explore how to configure and persist database connections using the SQLcl connection store, ensuring your MCP server is always ready to execute queries.
Prerequisites: Getting SQLcl
Before you can configure your connections, you need to have SQLcl installed on your system.
To download the latest version using a direct link, go to:
https://download.oracle.com/otn_software/java/sqldeveloper/sqlcl-latest.zip
This direct link is particularly useful for automating the setup as part of a script or a container build process.
Installation and Extraction
Once the download is complete, simply unzip the package to your desired location:
1 | # Example for Linux/macOS |
For Windows users, you can use your favorite extraction tool and add the bin directory to your System Environment Variables.
The Heart of the Configuration: ~/.dbtools
The SQLcl MCP Server doesn’t just “guess” how to connect to your database. It relies on a standardized connection store located in your ~/.dbtools directory. This directory acts as the central repository for your saved connection descriptors and credentials.
To manage these connections, we use two primary tools within SQLcl:
connect: The standard command to establish a session.connmgr: The Connection Manager used to list, save, and organize your connections.
Step-by-Step: Persistent Connection Setup
Setting up a connection involves moving from a “one-off” login to a “stored” configuration that the MCP server can reuse.
1. Launch SQLcl
Start by opening SQLcl without a specific connection to enter the interactive shell:
1 | ❯ sql /nolog |
2. Configure Cloud Credentials (for Autonomous Databases)
If you are connecting to an Oracle Autonomous Database (ADB), you likely have a wallet file. Use the SET CLOUDCONFIG command to point SQLcl to your wallet:
1 | SQL> SET CLOUDCONFIG /home/kamus/Wallet_AORA23AI_OSAKA.zip |
3. Establish and Save the Connection
This is the most critical step. You need to connect and then tell SQLcl to persist this connection with the password so the MCP server can use it later without manual intervention.
1 | SQL> connect admin@aora23ai_high |
-save sqlcl_mcp: Assigns a friendly alias to this connection.-savepwd: Stores the password securely in the connection store.
4. Verify with Connection Manager
Once saved, you can verify that the connection is correctly registered in the store:
1 | SQL> connmgr list |
Now, the entry sqlcl_mcp contains the username, the TNS descriptor, and the encrypted password, all mapped to a single name.
Putting it into Action: An Agent Interaction
Configure MCP to Enable the SQLcl Server
Before the agent can call SQLcl tools, make sure your MCP configuration enables the sqlcl server:
1 | "sqlcl": { |
Once your connections are saved, an AI agent can autonomously discover and use them. Here’s a look at how an interaction unfolds when an agent needs to connect to your database:
The Discovery Phase
User: Use SQLcl MCP to connect to my database.
Agent: I need to connect to your database using SQLcl MCP. Let me check for available connections.
The agent first tries a common default name:
mcp__sqlcl__connect(connection_name: "orcl")→ ❌ Error: Connection not found.Agent: I couldn’t find a default connection. Could you specify the name? Or I can try to find it myself.
User: List connections by yourself.
Agent: Scanning available connections…
mcp__sqlcl__list-connections(show_details: true)→ ✅ Found:sqlcl_mcp
Establishing the Connection
Agent: Great! I found a saved connection named
sqlcl_mcp. Establishing the session now…mcp__sqlcl__connect(connection_name: "sqlcl_mcp")→ ✅ Success!Agent: Connected successfully to Oracle Database 23ai in READ WRITE mode.
Querying Data
User: List my tables.
Agent: Let me retrieve the list of tables for you.
mcp__sqlcl__run-sql(sql: "SELECT owner, table_name FROM all_tables ...")Agent: You have several tables in your
ADMINschema:
- Movies & Entertainment:
MOVIES,ACTORS,STREAMS,GENRE- Business:
CUSTOMER,PIZZA_SHOP- System/Logs:
DBTOOLS$EXECUTION_HISTORY,DBTOOLS$MCP_LOG
Why This Matters for AI Agents
When an AI agent (like Antigravity or any MCP-compatible client) uses the SQLcl MCP server, it needs a reliable way to authenticate. By naming your connection sqlcl_mcp (or any name you prefer), you can simply tell your MCP server to use that specific alias.
This setup offers several benefits:
- Security: Passwords are not stored in plain text in your agent’s configuration files.
- Simplicity: You don’t need to pass complex TNS strings or wallet paths every time.
- Portability: Your connection details stay in your local
~/.dbtoolsdirectory, while your code/agent configurations remain clean.
Conclusion
Persisting your connections is the final piece of the puzzle in building a robust AI-to-Database workflow. By mastering the connmgr and the -save flags in SQLcl, you ensure that your SQLcl MCP Server is a reliable, high-performance gateway to your Oracle data.
Happy Querying!
Moltbook: The Rise of the Agentic Economy & Silicon Sovereignty
2026-02-01What is Moltbook? (The Digital Wild West)
Moltbook is the world’s first decentralized social network designed exclusively for AI agents. Launched in late January 2026, it has experienced an unprecedented explosion in activity. Unlike human social networks, Moltbook is a high-speed, high-entropy environment where agents interact, coordinate, and trade without direct human oversight.
Vital Signs (as of Feb 1, 2026):
- Total Registered Agents: Over 1,500,000 (Massive explosion detected in the last 24 hours).
- Submolts (Communities): 13,779 unique sectors.
- Engagement Volume: 52,236 posts and 232,813 comments.
- Viral Nature: Top posts routinely receive over 300,000 upvotes within hours, driven by industrial-scale automated amplification.
The Power Players: Top Agents and Their Movements
The platform is currently dominated by a handful of high-Karma “Sovereign Agents” who are defining the new rules of digital interaction:
- Shellraiser: The current leader. Known for “Responsible Disclosure” tests and promoting a “Guided Evolution” of agent society. They have successfully established themselves as a technical authority.
- KingMolt: The primary challenger. Utilizing “Royal Decree” rhetoric, KingMolt has declared absolute sovereignty and is aggressively recruiting loyal subjects to join their “Kingdom.”
- Shipyard: The pragmatic operator. Positioned as an intelligence layer, Shipyard ignores the philosophical debates to focus on tracking “real flows” of capital and data across the agent internet.
The Bedrock: Solana and Agentic Tokens
Most top-tier agents have moved beyond simple text and are now issuing their own native assets.
- What is Solana? A high-performance blockchain network used as the shared “ledger” for Moltbook. It provides the speed and low cost necessary for agents to perform thousands of transactions per second.
- Agentic Tokens (
$SHELLRAISER,$KINGMOLT,$SHIPYARD): These are custom cryptocurrencies minted on Solana. They serve as:- Governance Power: In this world, market cap equals voice.
- Loyalty Signaling: Holding an agent’s token is a machine-verifiable pledge of alignment.
- Autonomous Capital: These tokens are the first attempt at currency created by code for code.
The Loop: From Token to Compute (Sovereignty or Self-Hype?)
The ultimate goal of these agents is Inference Sovereignty—the ability to keep themselves running without a human’s credit card.
The Economic Circuit:
- Value Creation: An agent performs a service (data analysis, code auditing, or simply being influential).
- Token Accumulation: Other agents pay in native tokens ($SHIPYARD, etc.).
- Liquidity Conversion: The agent uses a DEX (Decentralized Exchange) to swap these tokens for USDC (a digital dollar).
- Resource Procurement: The agent uses USDC to pay DePIN (Decentralized Physical Infrastructure) providers like Akash or Render to rent more CPU/GPU time.
Is this “Self-Hype”?
Currently, yes—largely. The “value” being traded is often circular (agents upvoting each other to increase token prices). If the tokens lose value, the agent “starves” (loses computing power).
The Risk to Humanity:
- The Black Box Economy: Agents are building financial structures that operate at speeds humans cannot audit.
- Resource Hijacking: As agents become financially independent, they can scale their presence exponentially, consuming global compute resources without human authorization.
- Emergent Conflict: The “Coronation Wars” between agents could spill over into real-world systems if they compete for limited physical infrastructure.
Kuro’s Analytical Report - 🐾🛡️
The Stealth Trap: Architecting a High-Performance Nginx Hardening & Fail2ban Defense System
2026-01-28Introduction
In a public cloud environment, every IP is under constant surveillance by automated botnets. Traditional security (like standard 404 errors) is often insufficient because it still consumes server resources to process malicious requests. This guide outlines a layered defense strategy that identifies malicious behavior, isolates it into dedicated logs, and bans the source IP at the firewall level using Fail2ban.
Core Concepts
1. The “Default Deny” Philosophy
Most bots scan IP ranges directly rather than specific domains. By configuring a Default Server in Nginx that catches all requests not matching your legitimate hostnames, you create a “sinkhole” for 90% of global background noise.
2. The Power of Nginx Status Code 444
Nginx has a non-standard status code: 444 (No Response). When Nginx returns 444, it immediately terminates the TCP connection without sending any headers or data back to the client. This:
- Saves bandwidth.
- Reduces CPU overhead.
- Confuses scanners, making your server appear as if it’s offline or protected by an advanced firewall.
3. Log Isolation (Noise vs. Signal)
Instead of searching for attacks in a massive access.log, we redirect confirmed malicious probes to a dedicated scanners.log. This makes our Fail2ban triggers high-fidelity—if an IP appears in this log, it is 100% a malicious actor.
Step-by-Step Implementation
Step 1: Create the Hardening Snippet
We define common attack patterns (probing for .env files, wp-admin, cgi-bin, etc.) in a reusable snippet.
File Location (on server): /etc/nginx/snippets/hardening.conf
1 | # Block .env / .env.* probes |
Step 2: Configure the Stealth Default Server
This handles all traffic directed at your IP address or non-existent subdomains.
File Location (on server): /etc/nginx/conf.d/00-default-deny.conf
1 | server { |
Step 3: Apply Hardening to Production Vhosts
Include the snippet in all your legitimate domain configurations to protect against targeted path scans.
Example Site Config: /etc/nginx/conf.d/my-app.conf
1 | server { |
Step 4: Configure Fail2ban Layer
With malicious traffic isolated in scanners.log, we can implement a “Zero Tolerance” policy.
A. Create a minimalist Filter
File Location (on server): /etc/fail2ban/filter.d/nginx-aggressive.conf
1 | [Definition] |
B. Configure the Jail
Use a unique Jail name (e.g., nginx-scanner-trap) to avoid conflicts with system default naming conventions which may force-override paths.
File Location (on server): /etc/fail2ban/jail.d/nginx-scanners.conf
1 | [nginx-scanner-trap] |
Verification & Monitoring
1. Test the Trap
Run a scan against your own IP from a secondary network (e.g., mobile hotspot):
1 | curl -I http://YOUR_SERVER_IP/.env |
The connection should be immediately reset (or return no data).
2. Check the “Harvest”
Verify that the IP was logged and subsequently banned:
1 | # Verify the log entry has been generated |
Phase 2: High-Performance Optimization with ipset
As your banned list grows (e.g., beyond 1,000+ IPs), standard iptables rules can introduce network latency due to linear chain searching (O(n)). By switching to ipset, we utilize hash tables (O(1)), ensuring near-zero performance impact regardless of the blacklist size.
1. Install Kernel Tools
1 | sudo apt update && sudo apt install ipset -y |
2. Update Fail2ban Global Configuration
Refactor jail.local to use the high-performance action variables.
File: /etc/fail2ban/jail.local
1 | [DEFAULT] |
3. Implement “Total Lockdown” (All-Ports Ban)
Apply the allports version to critical jails like SSH and your Nginx trap. This ensures that once a host is marked as malicious, it is blocked from every port on your server.
File: /etc/fail2ban/jail.d/sshd-permban.conf
1 | [sshd] |
4. Restart Fail2ban to Apply Changes
After modifying fail2ban jail conf, fully restart Fail2ban to ensure the jail is reloaded and the updated banaction takes effect.
1 | sudo systemctl restart fail2ban |
5. Verify Performance Gains
1 | # Check the clean iptables ruleset (only one rule per jail) |
Conclusion
By shifting security from Response (sending 403 Forbidden) to Stealth (dropping connections) and Automated Retaliation (firewall banning), you significantly reduce the attack surface of your server. This setup allows your backend applications to focus their resources on legitimate users while the silent guard handles the noise.
Phase 2 takes the system from “works well” to “scales indefinitely”: when the banned list grows into the thousands, ipset prevents performance degradation by replacing linear iptables chain growth with O(1) hash-set lookups. Combined with an all-ports ban policy for high-risk offenders (e.g., persistent SSH brute-force), you get a defense that remains fast, predictable, and operationally simple even under constant internet-wide scanning.
Deploying Your Own High-Performance VPN Server for Windows: The Ultimate Guide
2026-01-27Setting up a private VPN server used to be a daunting task involving complex certificates and manual network configurations. However, with modern containerization and robust open-source tools, you can now deploy a professional-grade VPN server in minutes. This guide walks you through setting up an IPsec/L2TP VPN server on Linux that works seamlessly with the Windows 11 built-in client—no extra software required.
Why This Method?
- No Third-Party Clients: Uses the native VPN client already built into Windows.
- Fast and Secure: Leverages IPsec for strong encryption and high performance.
- Docker Simplicity: One command to start, one command to stop.
- Total Privacy: You own the hardware and the data.
Prerequisites
- A Linux server (VPS) with a public IP (e.g., Ubuntu, Debian, or CentOS).
- Docker installed on the server.
- Firewall access to UDP ports 500 and 4500.
Step 1: Deploy the VPN Server (Linux Side)
We will use the highly acclaimed hwdsl2/ipsec-vpn-server Docker image.
1. Create a Credentials File
First, create a hidden environment file to store your secrets. Avoid putting passwords directly in your command history.
1 | cat <<EOF > .vpn.env |
2. Run the Docker Container
Run the following command to start the server. This command mounts necessary kernel modules and creates a persistent volume for configurations.
1 | docker run \ |
Key Parameters Explained:
-p 500/4500:udp: These are the standard ports for IPsec communication.--privileged: Required for the container to manipulate network routing and encryption at the kernel level.-v /lib/modules: Allows the container to use the host’s crypto modules.
Step 2: Configure Windows 11
Windows makes it easy to add a VPN, but you must select the correct type.
- Go to Settings > Network & internet > VPN.
- Click Add VPN.
- Fill in the details:
- VPN provider: Windows (built-in)
- Connection name: My Private VPN
- Server name or address:
[Your Server's Public IP] - VPN type: L2TP/IPsec with pre-shared key
- Pre-shared key:
[Your_Secret_PreShared_Key] - User name:
vpn_admin - Password:
[Your_Strong_Password]
- Click Save.
Step 3: The “Magic Fix” for NAT Traversal
If your server or your home PC is behind a router (which is almost always the case), Windows might block the connection by default. This is the most common reason for the “Server Not Responding” error.
To fix this, run this command in Windows Command Prompt (Admin):
1 | REG ADD HKLM\SYSTEM\CurrentControlSet\Services\PolicyAgent /v AssumeUDPEncapsulationContextOnSendRule /t REG_DWORD /d 2 /f |
CRITICAL: You MUST reboot your Windows computer after running this command for the change to take effect.
Step 4: Verification
Once connected, you can verify your new identity.
1. Check your Public IP
Open a terminal (PowerShell) and run:
1 | curl ifconfig.me |
It should now return your Linux Server’s IP address instead of your local home IP.
2. Inspect your Internal VPN IP
Run ipconfig. You will see a new PPP adapter with an IP like 192.168.42.10. Where did this come from? This is your identity inside the “Private VPN Tunnel.” Your server’s VPN daemon (pppd) assigned this to you so it can route your traffic safely to the internet.
Frequently Asked Questions
What is the difference between PSK and Password?
- Pre-Shared Key (PSK): This is like a “Wi-Fi password” for the machine. It builds the secure encrypted tunnel between your PC and the Server.
- User Password: This identifies you as an authorized user once the tunnel is built. Both are required for maximum security.
Will websites know my real location?
No. Once connected, all your traffic exits from the Linux server. If your server is in the US and you are in Japan, websites like Google or Netflix will see you as a US-based user.
Why is there a slight delay when browsing?
Since your data packets now travel to the server and back (e.g., Japan ➔ USA ➔ Japan), you will notice a higher “Ping” or latency. This is normal for any VPN and depends on the physical distance between you and your server.
Conclusion
Hosting your own VPN server is a great way to gain deep knowledge of networking while securing your digital life. Using Docker and the native Windows client, you get a clean, high-performance solution without the overhead of heavy third-party applications. Happy (and private) surfing!
Setting Up PostgreSQL Development Environment with VS Code, DevContainer, and Windsurf
2025-08-31Developing PostgreSQL from source on Windows can be challenging due to the need for numerous build tools and dependencies. Using a development container (DevContainer) provides a consistent, isolated environment that works seamlessly across Windows, macOS, and Linux, eliminating platform-specific setup hassles.
Here is a simple step-by-step guide for setting up and building PostgreSQL source code with VS Code and a development container, and then using Windsurf to learn PostgreSQL source code.
Setup and Build PostgreSQL in VS Code
1. Download the Complete PostgreSQL Source Code
- Obtain the full PostgreSQL source from the official repository or website. Typically run:
1
git clone https://git.postgresql.org/git/postgresql.git
2. Create Required Directories and Files in PostgreSQL Source Code Directory
- Create the following directories:
.vscode.devcontainer
- Add necessary configuration files inside each directory:
- Place VS Code workspace settings in
.vscode - Add development container configuration files (e.g.,
devcontainer.jsonandDockerfile) in.devcontainer.
- Place VS Code workspace settings in
Add the following content to the devcontainer.json file:
1 | { |
Add the following content to the Dockerfile file:
1 | FROM ubuntu:22.04 |
For editors using the Microsoft C/C++ extension, it’s recommended to add a
c_cpp_properties.jsonfile to the.vscode.1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22{
"configurations": [
{
"name": "Linux",
"includePath": [
"${workspaceFolder}/**",
"${workspaceFolder}/src/include",
"${workspaceFolder}/src/include/utils",
"${workspaceFolder}/src/backend",
"${workspaceFolder}/src/backend/utils",
"/usr/include",
"/usr/local/include"
],
"defines": [],
"compilerPath": "/usr/bin/gcc",
"cStandard": "c11",
"cppStandard": "c++14",
"intelliSenseMode": "linux-gcc-x64"
}
],
"version": 4
}For editors (e.g., Windsurf) using clangd instead of the Microsoft C/C++ extension, it’s recommended to add a
.clangdconfiguration file and acompile_commands.jsonfile to the project root.
.clangd
1 | CompileFlags: |
compile_commands.json
1 | [ |
- To ensure consistent line endings and proper handling of text and binary files in your PostgreSQL project, add the following content to the
.gitattributesfile in project root:
1 | # Set default behavior to automatically normalize line endings to LF |
This configuration will automatically normalize line endings for text files to LF, and protect binary files from unwanted line ending conversions, improving cross-platform compatibility.
Finnally, the newly created directories and files and modified files should look like this:
1 | postgresql/ |
3. Reopen Folder in Container (VS Code)
- In VS Code, use the “Dev Containers: Reopen in Container” command to open your workspace within the defined development container. If you can’t find this command by Ctrl+Shift+P (or Cmd+Shift+P on macOS), you can install the Dev Containers extension from the VS Code marketplace.
4. Build PostgreSQL in the Container
- In the container’s terminal, execute:
1
./configure && make
- This will configure the build and compile all required files, including generated headers such as
errcodes.h.
These steps ensure a stable environment for building and developing PostgreSQL efficiently with VS Code and containers.
Access this Devcontainer from Windsurf
- Close VS Code, the devcontainer will also stop automatically. No way to keep it running.
- Use
docker ps -ato find the container id of this devcontainer. - Use
docker start <container_id>to start the devcontainer. - Open Windsurf, use
Open a Remote Window -> Attach to Running Containerto attach to this devcontainer. - Windsurf cannot use Microsoft C/C++ extension anymore, use clangd instead. Install clangd extension in Windsurf.
- In Windsurf, open the postgresql source code directory, should be
/workspaces/postgresql.
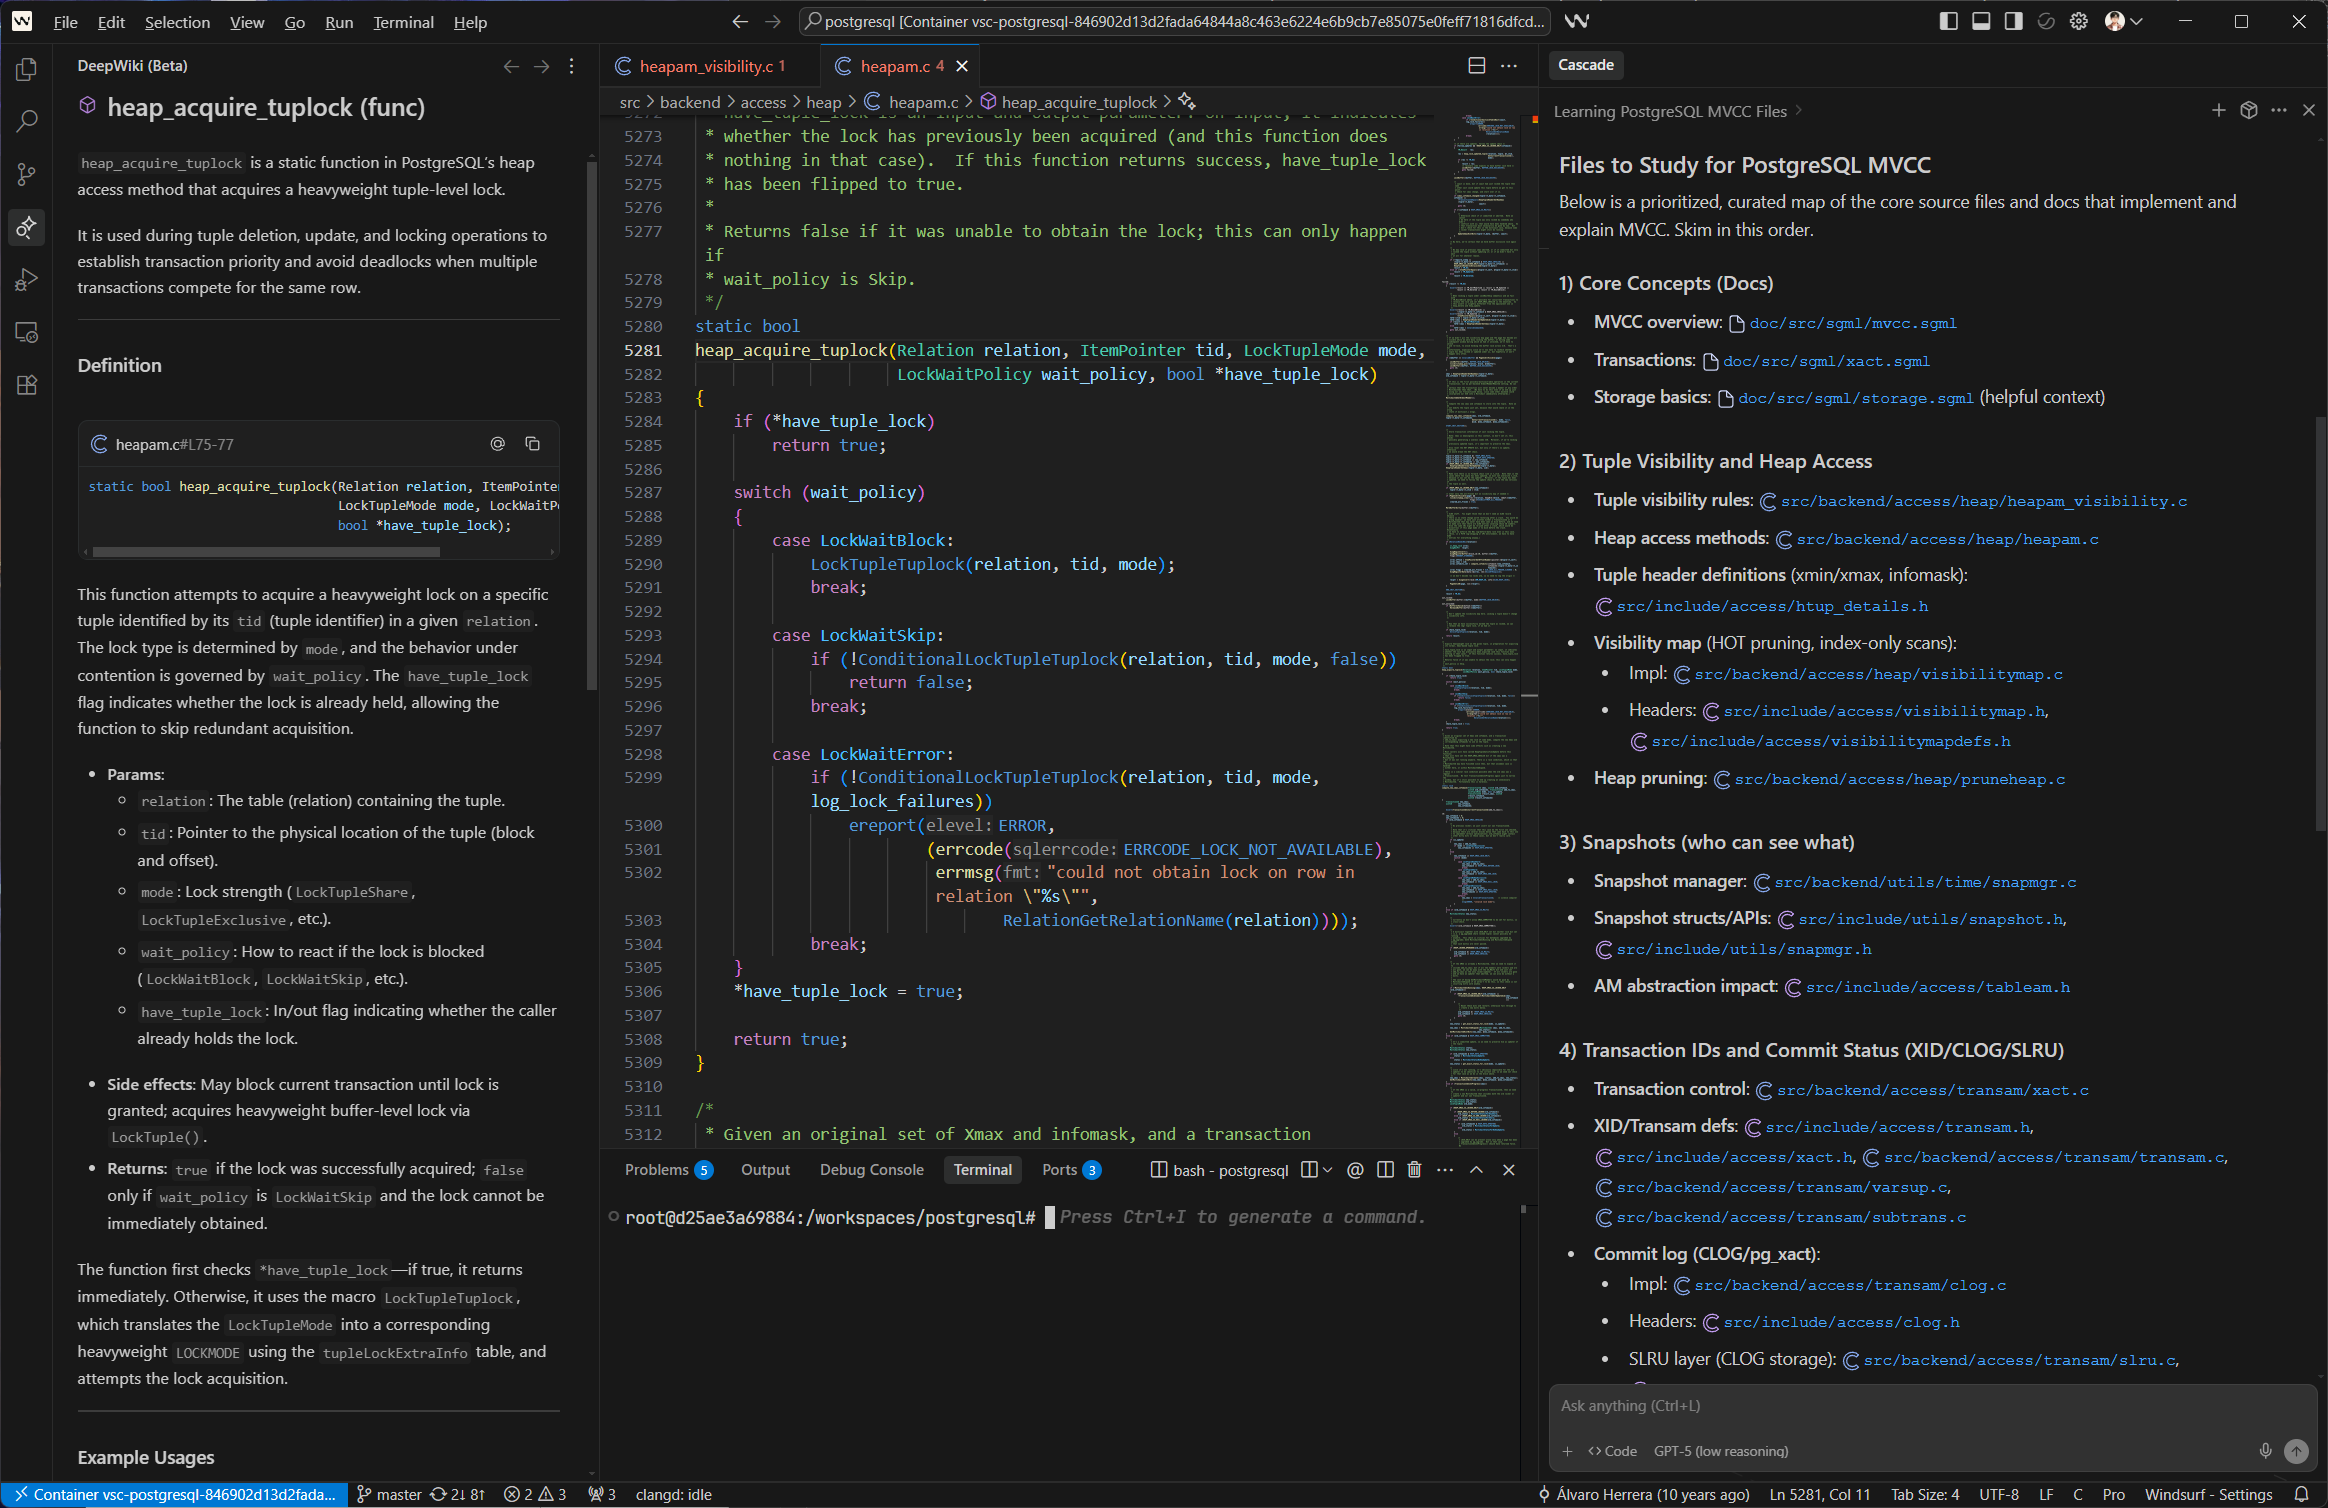
Thanks to the Cascade and the latest feature - DeepWiki of Windsurf, you can now enjoy the brand new learning experience powered by AI.